Floating-point arithmetic, part 1: rounding error
Floating-point arithmetic, part 1: rounding error
References:
- [1] D. Goldberg: “What Every Computer Scientist Should Know About Floating-Point Arithmetic”, ACM Computing Surveys, Vol. 23 Num. 1 pag. 5–48 (1991), DOI 10.1145/103162.103163
TL;DR
A floating-point number $x$ with base $\beta$ and precision $p$ can be written normalized (i.e. with first significat digit non-zero) as:
\[\boxed{ \begin{align*} x &= \pm\, d_0.d_1 d_2 \cdots d_{p-1} \times \beta^e \\[5pt] &= \pm\left(d_0 + d_1\,\beta^{-1} + \dots + d_{p-1}\,\beta^{-(p-1)}\right)\beta^e \, , \quad 0 \le d_i < \beta \end{align*} } \tag{1.1}\]Rounding a real number to the nearest floating-point number commits an error of at most half a unit in the last place (ulp), i.e. a relative error of at most the machine epsilon
\[\boxed{\varepsilon := \frac{\beta}{2}\,\beta^{-p}} \tag{2.4}\]- Guard digits: computing $x - y$ with only $p$ digits can give a relative error as large as $\beta - 1$ (Theorem 1); a single extra digit brings it below $2\varepsilon$ (Theorem 2).
- Cancellation: subtracting two nearby numbers that already carry rounding errors is catastrophic; subtracting exactly known numbers is benign. Many formulas can be rewritten so that only benign cancellations occur ($\oplus, \ominus, \otimes, \oslash$ are the computed operations, $\mathrm{LN}$ the computed logarithm):
| quantity | naive form | rewritten form |
|---|---|---|
| root of $ax^2 + bx + c$, with $b > 0$ | $\frac{-b + \sqrt{b^2 - 4ac}}{2a}$ | $\frac{2c}{-b - \sqrt{b^2 - 4ac}}$, Eq.(4.2) |
| $x^2 - y^2$ | $(x \otimes x) \ominus (y \otimes y)$ | $(x \ominus y) \otimes (x \oplus y)$ |
| area of a triangle | Heron’s formula, Eq.(4.4) | Kahan’s formula, Eq.(4.5) |
| $\ln(1 + x)$, with $x \ll 1$ | $\mathrm{LN}(1 \oplus x)$ | $x \otimes \mathrm{LN}(1 \oplus x) \oslash \big((1 \oplus x) \ominus 1\big)$, Eq.(4.8) |
- Exact rounding (compute exactly, then round to the nearest) with round half to even keeps $(x \ominus y) \oplus y$ from drifting (Theorem 5), allows to split a number into two half-precision parts (Theorem 6), and guarantees $(m \oslash n) \otimes n = m$ for $n = 2^i + 2^j$ (Theorem 7).
1. Floating-point formats
1.1 Representation
Squeezing infinitely many real numbers into a finite number of bits requires an approximate representation: the result of most computations with real numbers cannot be represented exactly, and must be rounded to fit back into the finite representation. The resulting rounding error is the characteristic feature of floating-point computation.
A floating-point representation has a base $\beta$ (always assumed to be even) and a precision $p$. A number is written as $\pm\, d.dd \cdots d \times \beta^e$, where the $p$-digit number $d.dd \cdots d$ is the significand (formerly called mantissa) and $e$ is the exponent. More precisely, $\pm\, d_0.d_1 d_2 \cdots d_{p-1} \times \beta^e$ represents the number
\[\pm\left(d_0 + d_1\,\beta^{-1} + \dots + d_{p-1}\,\beta^{-(p-1)}\right)\beta^e \, , \quad 0 \le d_i < \beta \tag{1.1}\]The term floating-point number means a real number that can be represented exactly in the format under discussion. The exponent is bounded, $e_{\min} \le e \le e_{\max}$.
Example: the number $0.1$.
- With $\beta = 10$ and $p = 3$, it is represented exactly as $1.00 \times 10^{-1}$.
- With $\beta = 2$ and $p = 24$, it cannot be represented exactly: $0.1$ has a finite decimal representation, but an infinite binary one. Doubling the fractional part over and over gives its binary digits one by one:
Keeping $p = 24$ digits (one before the binary point and 23 after it), the first discarded digits are $1100 \ldots$, more than half a unit of the last kept digit, so we round up:
\[\begin{align*} 0.1 &= 1.10011001100110011001100\,\big|\,1100 \ldots \times 2^{-4} \\[6pt] &\approx 1.10011001100110011001101 \times 2^{-4} \\[6pt] &= 13421773 \times 2^{-27} = 0.100000001490116119384765625 \end{align*} \tag{1.3}\]where $13421773$ is the 24-digit significand read as an integer, and $2^{-27} = 2^{-23} \times 2^{-4}$ is the weight of its last digit. $0.1$ lies strictly between the two consecutive floating-point numbers $13421772 \times 2^{-27} = 0.0999999940\ldots$ and $13421773 \times 2^{-27} = 0.1000000015\ldots$, so it is exactly representable by neither of them: the closest one is in error by $1.49 \times 10^{-9}$, i.e. by $0.2$ units of the last digit.
1.2 Encoding
There are $\beta^p$ possible significands and $e_{\max} - e_{\min} + 1$ possible exponents, so a floating-point number can be encoded in
\[\big\lceil \log_2(e_{\max} - e_{\min} + 1) \big\rceil + \big\lceil \log_2(\beta^p) \big\rceil + 1 \quad \mathrm{bits} \tag{1.4}\]where the final $+1$ is the sign bit. The precise encoding is not important for now. Two examples, not in [1]:
| format | exponent | significand | sign | total |
|---|---|---|---|---|
| $\beta = 2$, $p = 3$, $e_{\min} = -1$, $e_{\max} = 2$ | $\lceil \log_2 4 \rceil = 2$ | $\lceil \log_2 2^3 \rceil = 3$ | 1 | 6 |
| $\beta = 2$, $p = 24$, $e_{\min} = -126$, $e_{\max} = 127$ | $\lceil \log_2 254 \rceil = 8$ | $\lceil \log_2 2^{24} \rceil = 24$ | 1 | 33 |
The second one has the exponent range and the precision of IEEE single precision, which nevertheless fits in 32 bits: the leading digit of a normalized binary significand (Section 1.4) is always 1, so it does not need to be stored. This will be discussed in the next article.
1.3 Why a real number may not be representable
There are two reasons:
- the most common one: a real number with a finite representation in one base can have an infinite representation in another, like $0.1$ in Eq.(1.2). Then it lies strictly between two floating-point numbers;
- the number is out of range: its absolute value is larger than $\beta \times \beta^{e_{\max}}$ or smaller than $1.0 \times \beta^{e_{\min}}$.
This article (as Section 1 of [1]) deals with the first reason only; out-of-range numbers are discussed in Section 2 of [1].
1.4 Normalized numbers
Floating-point representations are not unique: both $0.01 \times 10^1$ and $1.00 \times 10^{-1}$ represent $0.1$. If the leading digit is nonzero, $d_0 \neq 0$ in Eq.(1.1), the representation is said to be normalized: $1.00 \times 10^{-1}$ is normalized, $0.01 \times 10^1$ is not. Requiring normalization makes the representation unique.
In a normalized significand $d_0$ can take $\beta - 1$ values and each of $d_1, \ldots, d_{p-1}$ can take $\beta$ values, so the number of positive normalized floating-point numbers is
\[(\beta - 1)\,\beta^{p-1}\,(e_{\max} - e_{\min} + 1) \tag{1.5}\]For $\beta = 2$, $p = 3$, $e_{\min} = -1$, $e_{\max} = 2$ (Figure 1 of [1]) this gives $1 \times 2^2 \times 4 = 16$ numbers. The significand $1.d_1 d_2$ is $1 + d_1/2 + d_2/4$, and the spacing between consecutive numbers with exponent $e$ is one unit of the last digit, $2^{-2} \times 2^e$:
| $e$ | $1.00 \times 2^e$ | $1.01 \times 2^e$ | $1.10 \times 2^e$ | $1.11 \times 2^e$ | spacing $2^{e-2}$ |
|---|---|---|---|---|---|
| $-1$ | $0.5$ | $0.625$ | $0.75$ | $0.875$ | $0.125$ |
| $0$ | $1$ | $1.25$ | $1.5$ | $1.75$ | $0.25$ |
| $1$ | $2$ | $2.5$ | $3$ | $3.5$ | $0.5$ |
| $2$ | $4$ | $5$ | $6$ | $7$ | $1$ |
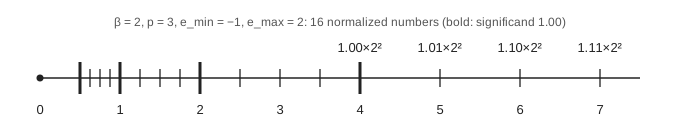
Each time the exponent grows by one, the spacing doubles: floating-point numbers are not uniformly distributed on the real line, it is their relative spacing that stays (roughly) constant. The bold marks are the numbers with significand $1.00$.
Normalization has a drawback: zero cannot be represented, since $d_0 \neq 0$. A natural way to represent it is $1.0 \times \beta^{e_{\min} - 1}$: this preserves the fact that the numerical ordering of nonnegative real numbers corresponds to the lexicographic ordering of their floating-point representations (assuming the exponent is stored to the left of the significand). It also means that, when the exponent is stored in a $k$-bit field, only $2^k - 1$ values are available for use as exponents, since one must be reserved to represent 0.
Notation: the $\times$ in a floating-point number is part of the notation, and different from a floating-point multiplication. For example, $(2.5 \times 10^{-3}) \times (4.0 \times 10^{2})$ involves only a single floating-point multiplication:
\[(2.5 \times 10^{-3}) \times (4.0 \times 10^{2}) = (2.5 \times 4.0) \times 10^{-3 + 2} = 10.0 \times 10^{-1} = 1.0 \times 10^{0}\]where the last step renormalizes the significand.
2. Relative error and ulps
Assumption: from now on, unless stated otherwise, $\beta = 10$ and $p = 3$, as in [1].
2.1 Units in the last place
If the result of a floating-point computation is $3.12 \times 10^{-2}$ and the answer computed with infinite precision is $0.0314$, the result is in error by 2 units in the last place. In general, if the floating-point number $d.d \cdots d \times \beta^e$ is used to represent the real number $z$, it is in error by
\[\abs{d.d \cdots d - \frac{z}{\beta^e}}\,\beta^{p-1} \quad \mathrm{ulps} \tag{2.1}\]units in the last place, as long as $\beta^{e_{\min}} \le z \le \beta^{e_{\max} + 1}$. Note that the exponent $e$ is the one of the floating-point number, not of $z$:
\[\begin{align*} 3.12 \times 10^{-2} \; \text{for} \; z = 0.0314 \, : &\quad \abs{3.12 - 3.14} \times 10^{2} = 2 \; \mathrm{ulps} \\[6pt] 3.14 \times 10^{-2} \; \text{for} \; z = 0.0314159 \, : &\quad \abs{3.14 - 3.14159} \times 10^{2} = 0.159 \; \mathrm{ulps} \end{align*}\]If the result of a calculation is the floating-point number nearest to the correct result, it can still be in error by as much as half an ulp.
2.2 Relative error
Another way to measure the difference between a floating-point number $\tilde{x}$ and the real number $x$ it approximates is the relative error:
\[\frac{\abs{\tilde{x} - x}}{\abs{x}} \tag{2.2}\]For example, approximating $3.14159$ by $3.14 \times 10^0$ commits the relative error $0.00159/3.14159 = 5.06 \times 10^{-4} \approx 0.0005$.
2.3 Half an ulp and the machine epsilon
When a real number is approximated by the closest floating-point number $d.dd \cdots dd \times \beta^e$, the absolute error can be as large as half an ulp, i.e. half a unit of the digit with weight $\beta^{-(p-1)}\beta^e$:
\[\frac{1}{2}\,\mathrm{ulp} = \frac{1}{2}\,\beta^{-(p-1)}\,\beta^{e} = \frac{\beta}{2}\,\beta^{-p}\,\beta^{e} = 0.\underbrace{0 \cdots 0}_{p-1}\Big(\frac{\beta}{2}\Big) \times \beta^{e}\]that is, the number whose only nonzero digit is $\beta/2$, in the $p$-th position after the point; for $\beta = 10$, $p = 3$ this is $0.005 \times 10^e$. All the numbers of the form $d.dd \cdots dd \times \beta^e$ have this same maximal absolute error, but their values range between $\beta^e$ and $\beta \times \beta^e$. So the corresponding relative error ranges between
\[\frac{(\beta/2)\,\beta^{-p}\,\beta^{e}}{\beta \times \beta^{e}} \quad \mathrm{and} \quad \frac{(\beta/2)\,\beta^{-p}\,\beta^{e}}{\beta^{e}}\] \[\Rightarrow \quad \frac{1}{2}\,\beta^{-p} \; \le \; \frac{1}{2}\,\mathrm{ulp} \; \le \; \frac{\beta}{2}\,\beta^{-p} \tag{2.3}\]where, as in [1], the middle term denotes the relative error corresponding to half an ulp. For $\beta = 10$, $p = 3$, Eq.(2.3) reads $0.0005 \le \frac{1}{2}\,\mathrm{ulp} \le 0.005$: half an ulp of the numbers with exponent 0 is $0.005$, which is a relative error of $0.005/1.00 = 0.005$ for $1.00$, but of only $0.005/9.99 = 0.0005005$ for $9.99$.
The relative error corresponding to half an ulp can thus vary by a factor of $\beta$, which is called the wobble. Setting the machine epsilon to the largest of the bounds in Eq.(2.3),
\[\boxed{\varepsilon := \frac{\beta}{2}\,\beta^{-p}} \tag{2.4}\]we can say that when a real number is rounded to the closest floating-point number, the relative error is always bounded by $\varepsilon$. Some values:
| format | $\varepsilon$ |
|---|---|
| $\beta = 10$, $p = 3$ | $5 \times 10^{-3} = 0.005$ |
| $\beta = 2$, $p = 24$ | $2^{-24} \approx 5.96 \times 10^{-8}$ |
| $\beta = 2$, $p = 53$ | $2^{-53} \approx 1.11 \times 10^{-16}$ |
To avoid such small numbers, relative errors are normally written as a factor times $\varepsilon$. For the approximation of $3.14159$ of Section 2.2:
\[\frac{0.00159/3.14159}{0.005}\,\varepsilon = \frac{5.06 \times 10^{-4}}{5 \times 10^{-3}}\,\varepsilon \approx 0.1\,\varepsilon\]2.4 Ulps versus relative error
Consider the real number $x = 12.35$. It is approximated by $\tilde{x} = 1.24 \times 10^1$ ($12.35$ is halfway between $12.3$ and $12.4$; both rounding rules of Section 5.2 give $12.4$). Next consider the computation $8x$: the exact value is $8x = 98.8$, while the computed value is $8\tilde{x} = 8 \times 12.4 = 99.2 = 9.92 \times 10^1$, which is exactly representable. Using Eq.(2.1) and Eq.(2.2):
\[\begin{align*} \tilde{x} = 1.24 \times 10^{1} \, : &\quad \abs{1.24 - 1.235} \times 10^{2} = 0.5 \; \mathrm{ulps} \, , \qquad \frac{0.05}{12.35} = 4.05 \times 10^{-3} = 0.81\,\varepsilon \\[6pt] 8\tilde{x} = 9.92 \times 10^{1} \, : &\quad \abs{9.92 - 9.88} \times 10^{2} = 4.0 \; \mathrm{ulps} \, , \qquad \frac{0.4}{98.8} = 4.05 \times 10^{-3} = 0.81\,\varepsilon \end{align*}\]The error measured in ulps is eight times larger, even though the relative error is the same: the absolute error has been multiplied by 8, but the ulp has not, since $\tilde{x}$ and $8\tilde{x}$ have the same exponent. In general, when the base is $\beta$, a fixed relative error expressed in ulps can wobble by a factor of up to $\beta$. Conversely, as Eq.(2.3) shows, a fixed error of half an ulp results in a relative error that can wobble by $\beta$.
2.5 Contaminated digits
When only the order of magnitude of the rounding error matters, ulps and $\varepsilon$ can be used interchangeably, since they differ by at most a factor of $\beta$. If a number is in error by $n$ ulps, or if the relative error of a computation is $n\varepsilon$, then
\[\mathrm{contaminated \; digits} \approx \log_\beta n \tag{2.5}\]For example, an error of $70.8$ ulps (Section 4.1) contaminates $\log_{10} 70.8 \approx 1.85$ digits, i.e. about 2 of the 3 digits.
The most natural way to measure the rounding error of a single operation is in ulps: rounding to the nearest floating-point number corresponds to an error of at most half an ulp. When analysing the rounding error caused by a formula, relative error is a better measure. Since $\varepsilon$ can overestimate the effect of rounding to the nearest floating-point number by the wobble factor $\beta$, error estimates of formulas are tighter on machines with a small $\beta$.
3. Guard digits
3.1 Exact difference, then rounding
One method of computing the difference between two floating-point numbers is to compute it exactly, then round it to the nearest floating-point number. With $p = 3$, $2.15 \times 10^{12} - 1.25 \times 10^{-5}$ is computed as
\[\begin{align*} x &= 2.15 \times 10^{12} \\[2pt] y &= 0.0000000000000000125 \times 10^{12} \\[2pt] x - y &= 2.1499999999999999875 \times 10^{12} \; \rightarrow \; 2.15 \times 10^{12} \end{align*}\]which is correct, but expensive when the operands differ greatly in size: here we needed 20 digits to produce a 3-digit result.
3.2 No guard digit
Floating-point hardware normally operates on a fixed number of digits. Suppose that only $p$ digits are kept, and that when the smaller operand is shifted right, the digits that fall off are simply discarded (truncation, not rounding). Then the example above becomes
\[\begin{align*} x &= 2.15 \times 10^{12} \\[2pt] y &= 0.00 \times 10^{12} \\[2pt] x - y &= 2.15 \times 10^{12} \end{align*}\]and the answer is the same as if the difference had been computed exactly, then rounded. But take $10.1 - 9.93$:
\[\begin{align*} x &= 1.01 \times 10^{1} \\[2pt] y &= 0.99 \times 10^{1} \qquad (9.93 = 0.993 \times 10^{1}, \text{ the last digit is shifted off}) \\[2pt] x - y &= 0.02 \times 10^{1} = 2.00 \times 10^{-1} \end{align*}\]The correct answer is $0.17 = 1.70 \times 10^{-1}$, so by Eq.(2.1) the computed difference is off by $\abs{2.00 - 1.70} \times 10^2 = 30$ ulps (a relative error of $0.03/0.17 = 0.18 = 35\,\varepsilon$), and it is wrong in every digit!
3.3 Theorem 1
How bad can the error be?
Theorem 1: Using a floating-point format with parameters $\beta$ and $p$ and computing differences using $p$ digits, the relative error of the result can be as large as $\beta - 1$.
Proof: take $x = 1.00 \cdots 0$ and $y = 0.\rho\rho \cdots \rho$, where $\rho = \beta - 1$ is the largest digit and $y$ has $p$ digits, all equal to $\rho$ (i.e. $y = \rho.\rho \cdots \rho \times \beta^{-1}$). Summing the geometric series:
\[y = \sum_{k=1}^{p} \rho\,\beta^{-k} = (\beta - 1)\,\frac{\beta^{-1}\left(1 - \beta^{-p}\right)}{1 - \beta^{-1}} = 1 - \beta^{-p} \quad \Rightarrow \quad x - y = \beta^{-p}\]To subtract, $y$ is aligned to the exponent of $x$: $0.\rho\rho \cdots \rho \times \beta^{0}$ has $p + 1$ digits (the leading 0 and the $p$ digits $\rho$), but only $p$ are kept, so the rightmost digit of $y$ gets shifted off:
\[\tilde{y} = 0.\underbrace{\rho \cdots \rho}_{p - 1} = 1 - \beta^{-(p-1)} \quad \Rightarrow \quad x - \tilde{y} = \beta^{-p+1}\] \[\Rightarrow \quad \mathrm{error} = \beta^{-p+1} - \beta^{-p} = \beta^{-p}(\beta - 1) \, , \qquad \mathrm{relative \; error} = \frac{\beta^{-p}(\beta - 1)}{\beta^{-p}} = \beta - 1 \qquad \blacksquare\]Two instances of the proof:
| $\beta = 10$, $p = 3$ | $\beta = 2$, $p = 3$ | |
|---|---|---|
| $x$ | $1.00$ | $1.00_2 = 1$ |
| $y$ | $0.999$ | $0.111_2 = 7/8$ |
| exact $x - y$ | $0.001$ | $0.001_2 = 1/8$ |
| $\tilde{y}$ | $0.99$ | $0.11_2 = 3/4$ |
| computed $x - y$ | $0.01$ | $0.01_2 = 1/4$ |
| relative error | $9$ | $1$ |
When $\beta = 2$, the absolute error can be as large as the result itself, and when $\beta = 10$ it can be nine times larger. To put it another way, for $\beta = 2$ we have $\varepsilon = 2^{-p}$, so a relative error of $1 = (1/\varepsilon)\,\varepsilon$ means by Eq.(2.5) $\log_2(1/\varepsilon) = \log_2(2^p) = p$ contaminated digits: all of the $p$ digits of the result are wrong!
3.4 One guard digit
Suppose one extra digit is added to guard against this situation (a guard digit): the smaller number is truncated to $p + 1$ digits, then the result of the subtraction is rounded to $p$ digits. With a guard digit, the previous example becomes
\[\begin{align*} x &= 1.010 \times 10^{1} \\[2pt] y &= 0.993 \times 10^{1} \\[2pt] x - y &= 0.017 \times 10^{1} = 1.70 \times 10^{-1} \end{align*}\]and the answer is exact. With a single guard digit, however, the relative error of the result may still be greater than $\varepsilon$, as in $110 - 8.59$:
\[\begin{align*} x &= 1.10 \times 10^{2} \\[2pt] y &= 0.085 \times 10^{2} \qquad (8.59 = 0.0859 \times 10^{2}, \text{ truncated to } p + 1 = 4 \text{ digits}) \\[2pt] x - y &= 1.015 \times 10^{2} \; \rightarrow \; 1.02 \times 10^{2} = 102 \end{align*}\]($1.015$ is a halfway case; both rounding rules of Section 5.2 give $1.02$). Compared with the correct answer $110 - 8.59 = 101.41$:
\[\frac{102 - 101.41}{101.41} = \frac{0.59}{101.41} = 5.8 \times 10^{-3} \approx 0.006 = 1.16\,\varepsilon \; > \; \varepsilon = 0.005\]The exactly rounded result would have been $101$, in error by only $0.41$ ulps: the truncated digit of $8.59$ is the one that would have decided the rounding.
3.5 Theorem 2
In general, the relative error of the result can be only slightly larger than $\varepsilon$:
Theorem 2: If $x$ and $y$ are floating-point numbers in a format with parameters $\beta$ and $p$, and if subtraction is done with $p + 1$ digits (i.e. one guard digit), then the relative rounding error in the result is less than $2\varepsilon$.
The theorem is proven in Section 4.1 of [1]. Addition is included in it, since $x$ and $y$ can be positive or negative. In the example above, $1.16\,\varepsilon < 2\varepsilon$.
4. Cancellation
Section 3 can be summarized by saying that without a guard digit, the relative error committed when subtracting two nearby quantities can be very large. In other words, the evaluation of any expression containing a subtraction (or an addition of quantities with opposite signs) could result in a relative error so large that all the digits are meaningless (Theorem 1). When subtracting nearby quantities, the most significant digits of the operands match and cancel each other.
Notation: to avoid confusion between exact and computed values, $x - y$ denotes the exact difference of $x$ and $y$, while $x \ominus y$ denotes the computed difference (i.e. with rounding error). Similarly, $\oplus$, $\otimes$ and $\oslash$ denote computed addition, multiplication and division. All caps indicate the computed value of a function, as in $\mathrm{LN}(x)$ or $\mathrm{SQRT}(x)$, while lowercase functions and the traditional notation, as in $\ln(x)$ and $\sqrt{x}$, denote their exact values.
4.1 Catastrophic and benign cancellation
There are two kinds of cancellation.
Catastrophic cancellation occurs when the operands are subject to rounding errors. For example, the quadratic formula contains the expression $b^2 - 4ac$. The quantities $b^2$ and $4ac$ are subject to rounding errors, since they are the results of floating-point multiplications: even if they are rounded to the nearest floating-point number, and so accurate to within half an ulp, their subtraction can make many of the accurate digits disappear, leaving behind mainly digits contaminated by rounding error. Example with $b = 3.34$, $a = 1.22$, $c = 2.28$:
\[\begin{align*} \text{exact:} &\quad b^2 = 11.1556 \, , \quad 4ac = 4 \times 2.7816 = 11.1264 \, , \quad b^2 - 4ac = 0.0292 \\[8pt] \text{floating point:} &\quad b \otimes b = 11.1556 \; \rightarrow \; 11.2 \\[4pt] &\quad a \otimes c = 2.7816 \; \rightarrow \; 2.78 \, , \quad 4 \otimes 2.78 = 11.12 \; \rightarrow \; 11.1 \\[4pt] &\quad (b \otimes b) \ominus (4 \otimes a \otimes c) = 11.2 - 11.1 = 0.100 \end{align*}\]($(4 \otimes a) \otimes c = 4.88 \otimes 2.28 = 11.1264 \rightarrow 11.1$ gives the same). By Eq.(2.1), the result $1.00 \times 10^{-1}$ is in error by $\abs{1.00 - 0.292} \times 10^2 = 70.8 \approx 70$ ulps, i.e. a relative error of $2.4 \approx 485\,\varepsilon$. The subtraction itself did not introduce any error, $11.2 - 11.1$ is exactly $0.1$: it rather exposed the errors introduced in the earlier multiplications,
\[\underbrace{0.1 - 0.0292}_{\mathrm{total \; error}} = 0.0708 = \underbrace{(11.2 - 11.1556)}_{\mathrm{error \; of} \; b \otimes b} - \underbrace{(11.1 - 11.1264)}_{\mathrm{error \; of} \; 4 \otimes a \otimes c} = 0.0444 + 0.0264\]Both product errors are within half an ulp ($0.05$), but they are not small compared with the small difference $0.0292$.
Benign cancellation occurs when subtracting exactly known quantities. If $x$ and $y$ have no rounding error, then by Theorem 2, if the subtraction is done with a guard digit, the difference $x \ominus y$ has a very small relative error (less than $2\varepsilon$).
A formula that exhibits catastrophic cancellation can sometimes be rearranged to eliminate the problem. The next sections show four examples.
4.2 The quadratic formula
The roots of $ax^2 + bx + c = 0$ are
\[r_1 = \frac{-b + \sqrt{b^2 - 4ac}}{2a} \, , \qquad r_2 = \frac{-b - \sqrt{b^2 - 4ac}}{2a} \tag{4.1}\]When $b^2 \gg ac$, $b^2 - 4ac$ does not involve a cancellation and $\sqrt{b^2 - 4ac} \approx \abs{b}$. But then the other addition (subtraction) in one of the two formulas, $-b \pm \sqrt{b^2 - 4ac}$, subtracts two nearly equal numbers, and the square root carries a rounding error: a catastrophic cancellation. To avoid it, we multiply the numerator and denominator of $r_1$ by $-b - \sqrt{b^2 - 4ac}$:
\[\begin{align*} r_1 &= \frac{-b + \sqrt{b^2 - 4ac}}{2a} \cdot \frac{-b - \sqrt{b^2 - 4ac}}{-b - \sqrt{b^2 - 4ac}} = \frac{b^2 - \left(b^2 - 4ac\right)}{2a\left(-b - \sqrt{b^2 - 4ac}\right)} \\[8pt] &= \frac{4ac}{2a\left(-b - \sqrt{b^2 - 4ac}\right)} = \frac{2c}{-b - \sqrt{b^2 - 4ac}} \end{align*}\]and similarly for $r_2$, multiplying by $-b + \sqrt{b^2 - 4ac}$:
\[r_1 = \frac{2c}{-b - \sqrt{b^2 - 4ac}} \, , \qquad r_2 = \frac{2c}{-b + \sqrt{b^2 - 4ac}} \tag{4.2}\]If $b^2 \gg ac$ and $b > 0$, computing $r_1$ with Eq.(4.1) involves a cancellation, so we use Eq.(4.2) for $r_1$ and Eq.(4.1) for $r_2$. If $b < 0$, we use Eq.(4.1) for $r_1$ and Eq.(4.2) for $r_2$. In both cases the sum that is actually computed is $-b - \mathrm{sign}(b)\sqrt{b^2 - 4ac}$, whose two terms have the same sign.
Example, not in [1]: $a = 1.00$, $b = 100$, $c = 1.00$.
\[\begin{align*} b \otimes b &= 1.00 \times 10^{4} \, , \quad 4 \otimes a \otimes c = 4.00 \\[4pt] (b \otimes b) \ominus 4.00 &= 9996 \; \rightarrow \; 1.00 \times 10^{4} \, , \quad \mathrm{SQRT}(1.00 \times 10^{4}) = 100 \\[8pt] \mathrm{Eq.(4.1)} \, : \quad r_1 &= (-100 \oplus 100) \oslash 2.00 = 0 \, , \qquad r_2 = (-100 \ominus 100) \oslash 2.00 = -100 \\[6pt] \mathrm{Eq.(4.2)} \, : \quad r_1 &= 2.00 \oslash (-100 \ominus 100) = 2.00 \oslash (-200) = -0.0100 \end{align*}\]The exact roots are $r_1 = -0.0100010002\ldots$ and $r_2 = -99.9899989998\ldots$. Eq.(4.1) gives a meaningless $r_1 = 0$, while $r_1$ from Eq.(4.2) and $r_2$ from Eq.(4.1) are both correct to all 3 digits (relative error $10^{-4} = 0.02\,\varepsilon$).
4.3 Difference of squares
The expression $x^2 - y^2$ is another formula that exhibits catastrophic cancellation. It is more accurate to evaluate it as
\[x^2 - y^2 = (x - y)(x + y) \tag{4.3}\]This form still has a subtraction, but it is a benign cancellation of quantities without rounding error. Example, not in [1], with $x = 3.34$ and $y = 3.33$ (exact $x^2 - y^2 = 0.0667$):
\[\begin{align*} (x \otimes x) \ominus (y \otimes y) &= (11.1556 \rightarrow 11.2) \ominus (11.0889 \rightarrow 11.1) = 0.100 \\[6pt] (x \ominus y) \otimes (x \oplus y) &= 0.01 \otimes 6.67 = 0.0667 \end{align*}\]The first result is in error by $33.3$ ulps (50%), the second one is exact.
By Theorem 2, the relative error of both $x \ominus y$ and $x \oplus y$ is at most $2\varepsilon$, and multiplying two quantities with a small relative error results in a product with a small relative error (Section 4.1 of [1]): with $\delta_1, \delta_2$ the relative errors of the subtraction and of the addition, and $\delta_3$ the one of the multiplication,
\[\begin{align*} (x \ominus y) \otimes (x \oplus y) &= (x - y)(1 + \delta_1)\,(x + y)(1 + \delta_2)\,(1 + \delta_3) \, , \qquad \abs{\delta_1}, \abs{\delta_2} \le 2\varepsilon \, , \; \abs{\delta_3} \le \varepsilon \\[6pt] &= (x^2 - y^2)\left(1 + \delta_1 + \delta_2 + \delta_3 + O(\varepsilon^2)\right) \, , \qquad \abs{\delta_1 + \delta_2 + \delta_3} \le 5\varepsilon \end{align*}\]Although $(x - y)(x + y)$ does not cause a catastrophic cancellation, it is slightly less accurate than $x^2 - y^2$ if $x \gg y$ or $x \ll y$: in this case $(x - y)(x + y)$ has three rounding errors, but $x^2 - y^2$ has only two, since the rounding error committed when computing the smaller of $x^2$ and $y^2$ does not affect the final subtraction (footnote 5 of [1]).
Inexact data: the floating-point numbers $x$ and $y$ might themselves be approximations of some true quantities $\hat{x}$ and $\hat{y}$, e.g. exactly known decimal numbers that cannot be expressed exactly in binary. Then, even though $x \ominus y$ is a good approximation of $x - y$, it can have a huge relative error compared with the true $\hat{x} - \hat{y}$. For example, if $\hat{x} = 3.344$ and $\hat{y} = 3.326$ are stored as $x = 3.34$ and $y = 3.33$, then $x \ominus y = 0.01$ is exact, but $\hat{x} - \hat{y} = 0.018$. So the advantage of $(x + y)(x - y)$ over $x^2 - y^2$ is not as dramatic with inexact data; since computing it is about the same amount of work, it is still clearly the preferred form. In general, replacing a catastrophic cancellation by a benign one is not worthwhile if the expense is large, because the input is often (not always) an approximation. But eliminating a cancellation entirely, as in the quadratic formula, is worthwhile even if the data are not exact.
Assumption: from now on, as in [1], the floating-point inputs to an algorithm are exact, and the results are computed as accurately as possible.
4.4 Area of a triangle
The area of a triangle can be expressed directly in terms of the lengths of its sides $a$, $b$ and $c$ with Heron’s formula:
\[A = \sqrt{s\,(s - a)(s - b)(s - c)} \, , \qquad s = \frac{a + b + c}{2} \tag{4.4}\]Suppose the triangle is very flat, i.e. $a \approx b + c$. Then $s \approx a$, and the term $s - a$ subtracts two nearby numbers, one of which ($s$) may have a rounding error. Example with $a = 9.0$, $b = c = 4.53$:
\[\begin{align*} \text{exact:} &\quad s = \frac{9.0 + 4.53 + 4.53}{2} = \frac{18.06}{2} = 9.03 \, , \quad s - a = 0.03 \, , \quad s - b = s - c = 4.50 \\[6pt] &\quad A = \sqrt{9.03 \times 0.03 \times 4.50 \times 4.50} = \sqrt{5.485725} = 2.34216 \ldots \end{align*}\] \[\begin{align*} \text{floating point:} \quad b \oplus c &= 9.06 \\[2pt] a \oplus (b \oplus c) &= 18.06 \; \rightarrow \; 18.1 \\[2pt] s = 18.1 \oslash 2 &= 9.05 \qquad (2 \; \mathrm{ulps \; off}) \\[2pt] s \ominus a &= 0.05 \qquad (\text{exact, but } 0.03 \text{ was the correct value}) \\[2pt] s \ominus b = s \ominus c &= 4.52 \\[2pt] s \otimes (s \ominus a) &= 0.4525 \; \rightarrow \; 0.452 \\[2pt] 0.452 \otimes (s \ominus b) &= 2.04304 \; \rightarrow \; 2.04 \\[2pt] 2.04 \otimes (s \ominus c) &= 9.2208 \; \rightarrow \; 9.22 \\[2pt] \mathrm{SQRT}(9.22) &= 3.0364 \ldots \; \rightarrow \; 3.04 \end{align*}\]Even though the computed value of $s$ is in error by only 2 ulps, the computed area $A = 3.04$ is in error by $\abs{3.04 - 2.34216} \times 10^2 = 69.8 \approx 70$ ulps. (Rounding the halfway case $0.4525$ up to $0.453$ instead gives $2.05$, $9.27$, and again $3.04$.)
Misprint in [1]: the ACM version states “an error of 60 ulps”; the error is $70$ ulps.
The order of the additions in $s$ matters too: $(a \oplus b) \oplus c = (13.53 \rightarrow 13.5) \oplus 4.53 = 18.03 \rightarrow 18.0$ gives $s = 9.00$, $s \ominus a = 0$, and $A = 0$.
There is a way to rewrite formula (4.4) so that it returns accurate results even for flat triangles (Kahan, 1986):
\[\boxed{A = \frac{1}{4}\sqrt{\big(a + (b + c)\big)\big(c - (a - b)\big)\big(c + (a - b)\big)\big(a + (b - c)\big)} \, , \qquad a \ge b \ge c} \tag{4.5}\]If $a$, $b$ and $c$ do not satisfy $a \ge b \ge c$, simply rename them before applying Eq.(4.5). Eq.(4.4) and Eq.(4.5) are algebraically identical:
\[\begin{align*} 2s &= a + b + c = a + (b + c) \\[2pt] 2(s - a) &= -a + b + c = c - (a - b) \\[2pt] 2(s - b) &= a - b + c = c + (a - b) \\[2pt] 2(s - c) &= a + b - c = a + (b - c) \end{align*}\] \[\Rightarrow \quad \big(a + (b + c)\big)\big(c - (a - b)\big)\big(c + (a - b)\big)\big(a + (b - c)\big) = 16\,s\,(s - a)(s - b)(s - c)\]and the square root of $16 A^2$, divided by 4, is $A$. The parentheses do not matter in exact arithmetic, but they decide the order of the floating-point operations. With the same values as above:
\[\begin{align*} a \oplus (b \oplus c) &= 9.0 \oplus 9.06 = 18.06 \; \rightarrow \; 18.1 \\[2pt] a \ominus b &= 9.0 - 4.53 = 4.47 \qquad (\text{exact}) \\[2pt] c \ominus (a \ominus b) &= 4.53 - 4.47 = 0.06 \qquad (\text{exact}) \\[2pt] c \oplus (a \ominus b) &= 4.53 + 4.47 = 9.00 \qquad (\text{exact}) \\[2pt] a \oplus (b \ominus c) &= 9.0 + 0 = 9.0 \\[6pt] 18.1 \otimes 0.06 &= 1.086 \; \rightarrow \; 1.09 \\[2pt] 1.09 \otimes 9.00 &= 9.81 \\[2pt] 9.81 \otimes 9.0 &= 88.29 \; \rightarrow \; 88.3 \\[2pt] \mathrm{SQRT}(88.3) &= 9.3968 \ldots \; \rightarrow \; 9.40 \\[2pt] 9.40 \oslash 4 &= 2.35 \end{align*}\]The computed area $2.35$ is in error by $\abs{2.35 - 2.34216} \times 10^2 = 0.78$ ulps, about 1 ulp, much more accurate than Heron’s formula: the relative error is $(2.35 - 2.34216)/2.34216 = 3.35 \times 10^{-3} = 0.67\,\varepsilon \approx 0.7\,\varepsilon$. The difference is in the small factor: in Heron’s formula, $s - a$ cancels $s$, which already carries a rounding error, while in Kahan’s formula the corresponding factor $c \ominus (a \ominus b)$ is computed exactly from exactly known data: both cancellations are benign.
Although formula (4.5) is much more accurate than (4.4) for this example, it would be nice to know how well (4.5) performs in general:
Theorem 3: The rounding error incurred when using Eq.(4.5) to compute the area of a triangle is at most $11\varepsilon$, provided subtraction is performed with a guard digit, $\varepsilon \le 0.005$, and square roots are computed to within half an ulp.
The condition $\varepsilon \le 0.005$ is met in virtually every actual floating-point system:
\[\begin{align*} \beta = 2 \, : &\quad \varepsilon = 2^{-p} \, , \qquad 2^{-7} = 0.0078 \, , \quad 2^{-8} = 0.0039 \qquad \Rightarrow \quad p \ge 8 \\[6pt] \beta = 10 \, : &\quad \varepsilon = 5 \times 10^{-p} \, , \quad 5 \times 10^{-2} = 0.05 \, , \quad 5 \times 10^{-3} = 0.005 \quad \Rightarrow \quad p \ge 3 \end{align*}\]In statements like Theorem 3, the relative error is that of the expression computed with floating-point arithmetic, i.e. of
\[\mathrm{SQRT}\Big(\big(a \oplus (b \oplus c)\big) \otimes \big(c \ominus (a \ominus b)\big) \otimes \big(c \oplus (a \ominus b)\big) \otimes \big(a \oplus (b \ominus c)\big)\Big) \oslash 4 \tag{4.6}\]Because of the cumbersome nature of Eq.(4.6), [1] usually says “the computed value of $E$” rather than writing out $E$ with circle notation.
Error bounds are usually too pessimistic: in the example above the relative error is $0.67\,\varepsilon$, much less than $11\varepsilon$. The main reason for computing error bounds is not to get precise bounds, but rather to verify that the formula does not contain numerical problems.
4.5 Compound interest and $\ln(1 + x)$
A final example of an expression that can be rewritten to use benign cancellation is $(1 + x)^n$, where $x \ll 1$. This expression arises in financial calculations. Consider depositing 100 USD every day into a bank account that earns an annual interest rate of $i = 6\%$, compounded daily, so that $n = 365$ and the daily rate is $j = i/n$. A deposit made $k$ days before the end of the year has grown to $100\,(1 + j)^k$, so the amount of money accumulated at the end of one year (deposits at the end of each day, $k = 0, \ldots, n - 1$) is the geometric sum
\[100 \sum_{k=0}^{n-1} (1 + j)^k = 100\,\frac{(1 + j)^n - 1}{(1 + j) - 1} = 100\,\frac{(1 + i/n)^n - 1}{i/n} \tag{4.7}\]Computed exactly:
\[\begin{align*} j = i/n &= 0.06/365 = 1.643835616 \times 10^{-4} \\[4pt] (1 + j)^n &= 1.0618313107 \\[4pt] 100\,\frac{(1 + j)^n - 1}{j} &= 100 \times \frac{0.0618313107}{1.643835616 \times 10^{-4}} = \$\,37614.05 \end{align*}\]Computed with $\beta = 2$ and $p = 24$ (single precision), the result is 37615.45 USD, a discrepancy of 1.40 USD. The reason is easy to see: $1 \oplus j$ involves adding 1 to $0.0001643836$, so the low-order bits of $j$ are lost, and this rounding error is amplified when $1 \oplus j$ is raised to the $n$-th power. In detail:
Step 1: near 1, the floating-point numbers are spaced by $2^{-23} = 1.19 \times 10^{-7}$, so
\[\frac{j}{2^{-23}} = 1378.95 \quad \Rightarrow \quad 1 \oplus j = 1 + 1379 \times 2^{-23} = 1.000164389610\]The computation actually uses the daily rate $\tilde{j} = (1 \oplus j) \ominus 1 = 1379 \times 2^{-23} = 1.64389610 \times 10^{-4}$: since $1379 < 2^{11}$, only 11 of the 24 bits of $j$ survive, and
\[\frac{\tilde{j} - j}{j} = \frac{6.05 \times 10^{-9}}{1.64 \times 10^{-4}} = 3.7 \times 10^{-5} \approx 617\,\varepsilon\]Step 2: raising to the $n$-th power multiplies the relative error by $n$:
\[\frac{(1 + \tilde{j})^n}{(1 + j)^n} - 1 = \left(1 + \frac{\tilde{j} - j}{1 + j}\right)^n - 1 \approx n\,\frac{\tilde{j} - j}{1 + j} = 365 \times 6.05 \times 10^{-9} = 2.21 \times 10^{-6}\]Step 3: subtracting 1 amplifies the relative error again, by a factor $(1 + j)^n / \big((1 + j)^n - 1\big) = 1.0618/0.0618 = 17.2$, giving $2.21 \times 10^{-6} \times 17.2 = 3.79 \times 10^{-5}$, i.e. $37614.05 \times 3.79 \times 10^{-5} = 1.43$ USD. Evaluating Eq.(4.7) exactly, but with $\tilde{j}$ instead of $j$ in the power, gives 37615.47 USD; the remaining single-precision roundings give the 37615.45 USD of [1].
The troublesome expression $(1 + i/n)^n$ can be rewritten as $\exp\left[n \ln(1 + i/n)\right]$, where now the problem is to compute $\ln(1 + x)$ for small $x$.
- One approach is to use the approximation $\ln(1 + x) \approx x$, in which case the payment becomes 37617.26 USD, off by 3.21 USD: even less accurate than the obvious formula. The approximation drops the $-x^2/2$ term of $\ln(1 + x) = x - x^2/2 + \dots$, i.e. $n j^2/2 = 4.9 \times 10^{-6}$ in the exponent, again amplified by the factor 17.2 of Step 3. (In exact arithmetic, $100\,(e^{0.06} - 1)/j = 37617.23$; single precision gives $37617.27$, which [1] reports as 37617.26.)
- There is a way to compute $\ln(1 + x)$ accurately, as Theorem 4 shows (Hewlett-Packard, 1982). This formula yields 37614.07 USD, accurate to within 2 cents!
Theorem 4: If $\ln(1 + x)$ is computed using formula (4.8), the relative error is at most $5\varepsilon$ when $0 \le x < 3/4$, provided subtraction is performed with a guard digit, $\varepsilon < 0.1$, and $\ln$ is computed to within half an ulp.
Misprint in [1]: the ACM version states “If $\ln(1 - x)$ is computed using the formula”; it is $\ln(1 + x)$.
In exact arithmetic the second line of Eq.(4.8) is just $\ln(1 + x)$; what matters is that it is computed as $x \otimes \mathrm{LN}(1 \oplus x) \oslash \big((1 \oplus x) \ominus 1\big)$. Theorem 4 assumes that $\mathrm{LN}(x)$ approximates $\ln(x)$ to within half an ulp. The problem it solves is that when $x$ is small, $\mathrm{LN}(1 \oplus x)$ is not close to $\ln(1 + x)$, because $1 \oplus x$ has lost the information in the low-order bits of $x$. That is, the computed value of $\ln(1 + x)$ is not close to its actual value when $x \ll 1$.
The formula works for any value of $x$, but it is only interesting for $x \ll 1$, which is where catastrophic cancellation occurs in the naive formula $\ln(1 + x)$. Although it may seem mysterious, there is a simple explanation for why it works. Write
\[\ln(1 + x) = x\,\frac{\ln(1 + x)}{x} = x\,\mu(x) \, , \qquad \mu(x) := \frac{\ln(1 + x)}{x} = 1 - \frac{x}{2} + \frac{x^2}{3} - \dots \tag{4.9}\]- The left factor $x$ can be computed exactly, but the right factor $\mu(x)$ will suffer a large rounding error when adding 1 to $x$.
- However, $\mu$ is almost constant, since $\ln(1 + x) \approx x$: by Eq.(4.9), $\mu(\tilde{x}) - \mu(x) \approx -(\tilde{x} - x)/2$. So changing $x$ slightly will not introduce much error: if $\tilde{x} \approx x$, computing $x\,\mu(\tilde{x})$ is a good approximation of $x\,\mu(x) = \ln(1 + x)$.
- Is there a value $\tilde{x}$ for which $\tilde{x}$ and $\tilde{x} + 1$ can be computed accurately? There is: $\tilde{x} = (1 \oplus x) \ominus 1$, because then $1 + \tilde{x}$ is exactly equal to $1 \oplus x$ (and the subtraction is a benign cancellation, exact with a guard digit). So $\mathrm{LN}(1 \oplus x) \oslash \tilde{x}$ is an accurate value of $\mu(\tilde{x})$.
In the compound interest example (single precision):
| quantity | value | relative error vs exact |
|---|---|---|
| $\ln(1 + j)$, exact | $1.643700521 \times 10^{-4}$ | |
| $\mathrm{LN}(1 \oplus j)$ | $1.643761060 \times 10^{-4}$ | $3.7 \times 10^{-5}$ |
| $\mu(j)$, exact | $0.9999178172$ | |
| $\mu(\tilde{j})$, exact | $0.9999178142$ | $3.0 \times 10^{-9}$ |
| $j \otimes \mathrm{LN}(1 \oplus j) \oslash \big((1 \oplus j) \ominus 1\big)$ | $1.643700525 \times 10^{-4}$ | $2.2 \times 10^{-9} = 0.04\,\varepsilon$ |
The $3.7 \times 10^{-5}$ error of $\tilde{j}$ that ruins $\mathrm{LN}(1 \oplus j)$ changes $\mu$ by only $3.0 \times 10^{-9}$.
The same mechanism with $\beta = 10$, $p = 3$, and $x = 0.0123$ (not in [1]):
\[\begin{align*} 1 \oplus x &= 1.0123 \; \rightarrow \; 1.01 \\[6pt] \text{exact:} \quad \ln(1 + x) &= \ln(1.0123) = 0.0122250 \ldots \\[6pt] \text{naive:} \quad \mathrm{LN}(1 \oplus x) &= \mathrm{LN}(1.01) = 0.00995033 \ldots \; \rightarrow \; 0.00995 \\[6pt] \text{Theorem 4:} \quad \tilde{x} &= (1 \oplus x) \ominus 1 = 0.01 \\[2pt] x \otimes \mathrm{LN}(1 \oplus x) &= 0.0123 \times 0.00995 = 0.000122385 \; \rightarrow \; 0.000122 \\[2pt] 0.000122 \oslash \tilde{x} &= 0.0122 \end{align*}\]The naive result has a relative error of 19% ($37\,\varepsilon$), the one of Theorem 4 of 0.2% ($0.41\,\varepsilon$): $\tilde{x} = 0.01$ differs from $x = 0.0123$ by 19%, but $\mu(0.01) = 0.99503$ differs from $\mu(0.0123) = 0.99390$ by only 0.11%.
4.6 The price of a guard digit
The results of this section can be summarized by saying that a guard digit guarantees accuracy when nearby precisely known quantities are subtracted (benign cancellation). Sometimes a formula that gives inaccurate results can be rewritten to have much higher numerical accuracy by using benign cancellation; however, the procedure only works if subtraction is performed using a guard digit.
The price of a guard digit is not high, because it merely requires making the adder 1 bit wider: for a 54-bit double precision adder, the additional cost is $1/54 = 1.9\% < 2\%$. For this price, you gain the ability to run many algorithms, such as Kahan’s formula (4.5) for computing the area of a triangle ([1] says formula (6), but it is the one that requires the guard digit, i.e. their (7)) and the expression of Theorem 4 for computing $\ln(1 + x)$. Although most modern computers (in 1991) have a guard digit, there are a few, such as Crays, that do not.
5. Exactly rounded operations
5.1 Definition
When floating-point operations are done with a guard digit, they are not as accurate as if they were computed exactly, then rounded to the nearest floating-point number. Operations performed in this manner are called exactly rounded. The example $110 - 8.59$ of Section 3.4 shows that a single guard digit does not always give exactly rounded results ($102$ instead of $101$). Section 4 gave several examples of algorithms that require a guard digit in order to work properly; this section gives examples of algorithms that require exact rounding.
5.2 Halfway cases: round half up or round half to even
Rounding is straightforward, with the exception of how to round halfway cases: should $12.5$ round to $12$ or $13$?
- Round half up: one school of thought divides the 10 digits in half, letting $\lbrace 0, 1, 2, 3, 4 \rbrace$ round down and $\lbrace 5, 6, 7, 8, 9 \rbrace$ round up; thus $12.5$ rounds to $13$. This is how rounding works on Digital Equipment Corporation’s VAX computers.
- Round half to even: since numbers ending in 5 are halfway between two possible roundings, they should round down half of the time and round up the other half. One way of obtaining this behaviour is to require the rounded result to have its least significant digit even: $12.5$ rounds to $12$, because 2 is even.
Reiser and Knuth (1975) offer the following reason for preferring round to even:
Theorem 5: Let $x$ and $y$ be floating-point numbers, and define $x_0 = x$, $x_1 = (x_0 \ominus y) \oplus y$, …, $x_n = (x_{n-1} \ominus y) \oplus y$. If $\oplus$ and $\ominus$ are exactly rounded using round to even, then either $x_n = x$ for all $n$, or $x_n = x_1$ for all $n \ge 1$.
[1] does not include a proof. To clarify the result, take $\beta = 10$, $p = 3$, $x = 1.00$, $y = -0.555$:
\[\begin{align*} \text{round half up:} \quad x_0 \ominus y &= 1.00 + 0.555 = 1.555 \; \rightarrow \; 1.56 \\[2pt] x_1 = 1.56 \oplus y &= 1.56 - 0.555 = 1.005 \; \rightarrow \; 1.01 \\[2pt] x_1 \ominus y &= 1.01 + 0.555 = 1.565 \; \rightarrow \; 1.57 \\[2pt] x_2 = 1.57 \oplus y &= 1.57 - 0.555 = 1.015 \; \rightarrow \; 1.02 \\[2pt] &\;\;\vdots \\[2pt] x_n &= 1.00 + 0.01\,n \\[10pt] \text{round half to even:} \quad x_0 \ominus y &= 1.555 \; \rightarrow \; 1.56 \qquad (6 \text{ is even}) \\[2pt] x_1 = 1.56 \oplus y &= 1.005 \; \rightarrow \; 1.00 \qquad (0 \text{ is even}) \\[2pt] x_n &= 1.00 \quad \forall\, n \end{align*}\]All the exact intermediate results have 4 digits ending in 5, i.e. they are halfway cases: round half up rounds all of them up, so each successive value of $x_n$ increases by $0.01$, while round half to even rounds up once and down once. How far does the drift go? (not in [1]): $845$ steps, up to $x_{845} = 9.45$. There, $9.45 + 0.555 = 10.005 \rightarrow 10.0$ is no longer a halfway case (the result has exponent 1, and its last digit has weight $0.1$), and $10.0 - 0.555 = 9.445 \rightarrow 9.45 = x_{845}$.
This example suggests that when using the round up rule, computations can gradually drift upward, whereas when using round to even the theorem says this cannot happen. Throughout the rest of [1], round to even is used.
5.3 Multiple precision: splitting a number
One application of exact rounding occurs in multiple precision arithmetic. There are two basic approaches to higher precision:
- represent floating-point numbers using a very large significand, stored in an array of words, and code the routines for manipulating these numbers in assembly language;
- represent higher precision floating-point numbers as an array of ordinary floating-point numbers, where adding the elements of the array in infinite precision recovers the high precision floating-point number.
[1] discusses the second approach: it can be coded portably in a high-level language, but it requires exactly rounded arithmetic.
The key to multiplication in this system is representing a product $xy$ as a sum, where each summand has the same precision as $x$ and $y$. This can be done by splitting $x$ and $y$: writing $x = x_h + x_l$ and $y = y_h + y_l$,
\[xy = x_h\,y_h + x_h\,y_l + x_l\,y_h + x_l\,y_l \tag{5.1}\]If $x$ and $y$ have $p$-bit significands, the summands will also have $p$-bit significands, provided $x_l$, $x_h$, $y_h$, $y_l$ can be represented using $\lfloor p/2 \rfloor$ bits (the product of two numbers with $\lfloor p/2 \rfloor$ bits has at most $2 \lfloor p/2 \rfloor \le p$ bits). When $p$ is even, it is easy to find a splitting: the number $x_0.x_1 \cdots x_{p-1}$ can be written as the sum
\[x_0.x_1 \cdots x_{p-1} = x_0.x_1 \cdots x_{p/2 - 1} + 0.0 \cdots 0\,x_{p/2} \cdots x_{p-1}\]When $p$ is odd, this simple splitting method will not work, since one of the two halves has $\lceil p/2 \rceil$ digits. An extra bit can, however, be gained by using negative numbers. For example, with $\beta = 2$, $p = 5$ and $x = 0.10111_2$:
\[x = 0.10111_2 = \frac{23}{32} = \underbrace{0.11_2}_{x_h \, = \, 24/32} \; \underbrace{- \; 0.00001_2}_{x_l \, = \, -1/32}\]where $x_h$ has 2 significant bits and $x_l$ has 1, both at most $\lfloor 5/2 \rfloor = 2$, while the digit splitting $0.10_2 + 0.00111_2$ would need 3 significant bits for the second part.
There is more than one way to split a number. A splitting method that is easy to compute is due to Dekker (1971), but it requires more than a single guard digit:
\[\boxed{x_h = (m \otimes x) \ominus (m \otimes x \ominus x) \, , \qquad x_l = x \ominus x_h} \tag{5.2}\]Theorem 6: Let $p$ be the floating-point precision, with the restriction that $p$ is even when $\beta > 2$, and assume that floating-point operations are exactly rounded. Then if $k = \lceil p/2 \rceil$ is half the precision (rounded up) and $m = \beta^k + 1$, $x$ can be split as $x = x_h + x_l$, where $x_h$ and $x_l$ are given by Eq.(5.2), and each of them is representable using $\lfloor p/2 \rfloor$ bits of precision.
To see how this theorem works, take $\beta = 10$, $p = 4$, $b = 3.476$, $a = 3.463$, $c = 3.479$, and compute $b^2 - ac$:
\[\begin{align*} \text{exact:} &\quad b^2 = 12.082576 \, , \quad ac = 12.047777 \, , \quad b^2 - ac = 0.034799 \; \rightarrow \; 0.03480 \\[6pt] \text{naive:} &\quad b \otimes b = 12.08 \, , \quad a \otimes c = 12.05 \, , \quad (b \otimes b) \ominus (a \otimes c) = 0.03 \end{align*}\]By Eq.(2.1) with $p = 4$, the naive result $3.000 \times 10^{-2}$ is in error by $\abs{3.000 - 3.4799} \times 10^3 = 479.9 \approx 480$ ulps. Now split $a$, $b$ and $c$ with Eq.(5.2): $k = \lceil 4/2 \rceil = 2$ and $m = 10^2 + 1 = 101$.
| $x$ | $m \otimes x$ | $m \otimes x \ominus x$ | $x_h$ | $x_l = x \ominus x_h$ |
|---|---|---|---|---|
| $b = 3.476$ | $351.076 \to 351.1$ | $347.624 \to 347.6$ | $351.1 - 347.6 = 3.5$ | $-0.024$ |
| $a = 3.463$ | $349.763 \to 349.8$ | $346.337 \to 346.3$ | $349.8 - 346.3 = 3.5$ | $-0.037$ |
| $c = 3.479$ | $351.379 \to 351.4$ | $347.921 \to 347.9$ | $351.4 - 347.9 = 3.5$ | $-0.021$ |
So $b = 3.5 - 0.024$, $a = 3.5 - 0.037$, $c = 3.5 - 0.021$, and with Eq.(5.1) each product is exact with $p = 4$ digits:
\[\begin{align*} b^2 &= 3.5^2 - 2 \times 3.5 \times 0.024 + 0.024^2 = 12.25 - 0.168 + 0.000576 \\[6pt] ac &= 3.5^2 - (3.5 \times 0.037 + 3.5 \times 0.021) + 0.037 \times 0.021 \\[2pt] &= 12.25 - (0.1295 + 0.0735) + 0.000777 = 12.25 - 0.2030 + 0.000777 \end{align*}\]where the sums are left unevaluated. Finally, subtracting these two series term by term:
\[\begin{align*} b^2 - ac &= (12.25 - 12.25) \oplus (0.2030 - 0.168) \ominus (0.000777 - 0.000576) \\[6pt] &= 0 \oplus 0.0350 \ominus 0.000201 = 0.034799 \; \rightarrow \; 0.03480 \end{align*}\]which is identical to the exactly rounded result.
Misprint in [1]: the ACM version prints “$0 \oplus .0350 \ominus .04685 = .03480$”; the last term is $0.000777 - 0.000576 = 0.000201$.
To show that Theorem 6 really requires exact rounding, take $\beta = 2$, $p = 3$ and $x = 7 = 111_2$. Then $k = \lceil 3/2 \rceil = 2$, $m = 2^2 + 1 = 5$, and
\[m\,x = 35 = 100011_2 \; \rightarrow \; m \otimes x = 100000_2 = 32 \qquad (35 - 32 = 3 \; < \; 40 - 35 = 5)\]- with exact rounding: $m \otimes x \ominus x = 32 - 7 = 25 = 11001_2 \rightarrow 11000_2 = 24$, so $x_h = 32 \ominus 24 = 8 = 1_2 \times 2^3$ and $x_l = 7 \ominus 8 = -1$: both representable with $\lfloor 3/2 \rfloor = 1$ bit;
- with a single guard digit: $7 = 1.11_2 \times 2^2 = 0.00111_2 \times 2^5$ is truncated to $p + 1 = 4$ digits, $0.001_2 \times 2^5 = 4$, and $32 - 4 = 28 = 11100_2$, exactly representable. So $m \otimes x \ominus x = 28$, $x_h = 32 - 28 = 4$ and $x_l = 7 - 4 = 3 = 11_2$, which is not representable with $\lfloor p/2 \rfloor = 1$ bit.
5.4 Theorem 7
As a final example of exact rounding, consider dividing $m$ by 10. The result is a floating-point number that will in general not be equal to $m/10$. When $\beta = 2$, however, multiplying $m \oslash 10$ by 10 will miraculously restore $m$, provided exact rounding is being used. Actually, a more general fact (due to Kahan) is true:
Theorem 7: When $\beta = 2$, if $m$ and $n$ are integers with $\abs{m} < 2^{p-1}$ and $n$ has the special form $n = 2^i + 2^j$, then $(m \oslash n) \otimes n = m$, provided floating-point operations are exactly rounded.
The proof is ingenious (see [1], pp. 14–15), and skipped here. For the example above, $10 = 2^3 + 2^1$. The theorem holds true for any base $\beta$, as long as $2^i + 2^j$ is replaced by $\beta^i + \beta^j$. As $\beta$ gets larger, however, there are fewer and fewer denominators of this form. Up to 100:
| $\beta$ | $n = \beta^i + \beta^j \le 100$ | count |
|---|---|---|
| 2 | 2, 3, 4, 5, 6, 8, 9, 10, 12, 16, 17, 18, 20, 24, 32, 33, 34, 36, 40, 48, 64, 65, 66, 68, 72, 80, 96 | 27 |
| 10 | 2, 11, 20 | 3 |
Numerical check in IEEE double precision ($\beta = 2$, $p = 53$), where m/n*n in most programming languages computes exactly $(m \oslash n) \otimes n$ (not in [1]):
since the double precision numbers between 2 and 4 are spaced $2^{-51} = 4.4 \times 10^{-16}$, and the exact product is only $1.1 \times 10^{-16}$ below 3. Counting the failures of $(m \oslash n) \otimes n = m$ for $m = 1, \ldots, 2^{20} - 1$:
| $n$ | binary form | failures |
|---|---|---|
| 3 | $2^1 + 2^0$ | 0 |
| 10 | $2^3 + 2^1$ | 0 |
| 12 | $2^3 + 2^2$ | 0 |
| 7 | $2^2 + 2^1 + 2^0$ | 74892 |
| 49 | $2^5 + 2^4 + 2^0$ | 160502 |
| 100 | $2^6 + 2^5 + 2^2$ | 146800 |
For example, $(1 \oslash 49) \otimes 49 = 0.9999999999999999 \neq 1$.
5.5 Does it matter?
We are now in a position to answer the question: does it matter if the basic arithmetic operations introduce a little more rounding error than necessary? The answer is that it does matter, because accurate basic operations enable us to prove that formulas are “correct”, in the sense that they have a small relative error. Section 4 discussed several algorithms that require guard digits to produce correct results in this sense. If the inputs to those formulas are numbers representing imprecise measurements, however, the bounds of Theorems 3 and 4 become less interesting. The reason is that the benign cancellation $x - y$ can become catastrophic if $x$ and $y$ are only approximations of some measured quantity. But accurate operations are useful even in the face of inexact data, because they enable us to establish exact relationships like those of Theorems 6 and 7. These are useful even if every floating-point variable is only an approximation of some actual value.
6. Reproducing the computations
All the base-10 examples above can be reproduced with Python’s decimal module: a Context(prec=p) performs exactly rounded $+$, $-$, $\times$, $/$, $\sqrt{\cdot}$ and $\ln$ with $p$ significant digits, and the rounding of halfway cases can be chosen (ROUND_HALF_EVEN or ROUND_HALF_UP). The truncating subtraction of Section 3 (with or without guard digit) has to be written by hand. The single precision examples can be reproduced with numpy.float32, computing $\ln$ and $\exp$ in double precision and rounding them to single, so that they are accurate to within half an ulp as assumed by Theorem 4 (numpy’s own float32 exponential is off by 2 ulps in this example, which changes the result by about 7 cents).
from decimal import Decimal as D, Context, ROUND_HALF_EVEN
c3 = Context(prec=3, rounding=ROUND_HALF_EVEN)      # beta = 10, p = 3, exactly rounded

# catastrophic cancellation, Section 4.1
b, a, c = D("3.34"), D("1.22"), D("2.28")
bb  = c3.multiply(b, b)                             # 11.1556 -> 11.2
ac4 = c3.multiply(D(4), c3.multiply(a, c))          # 4 * 2.78 = 11.12 -> 11.1
print(c3.subtract(bb, ac4), b*b - 4*a*c)            # 0.1   0.0292

# Kahan's formula (4.5), Section 4.4
a, b, c = D("9.0"), D("4.53"), D("4.53")
amb  = c3.subtract(a, b)                            # 4.47, exact
prod = c3.multiply(c3.multiply(c3.multiply(
           c3.add(a, c3.add(b, c)), c3.subtract(c, amb)),
           c3.add(c, amb)), c3.add(a, c3.subtract(b, c)))
print(c3.divide(c3.sqrt(prod), D(4)))               # 2.35

# compound interest, Section 4.5: beta = 2, p = 24
import numpy as np
f = np.float32
j = f(0.06) / f(365)
w = f(1) + j                                        # 1 + 1379 * 2^-23
P = f(1)
for _ in range(365):
    P = P * w                                       # (1 (+) j)^n
print(f(100) * ((P - f(1)) / j))                    # 37615.453

LN  = lambda v: f(np.log(np.float64(v)))            # ln, exp correctly rounded to float32
EXP = lambda v: f(np.exp(np.float64(v)))
ln1p = j * LN(w) / (w - f(1))                       # Theorem 4
P4 = EXP(f(365) * ln1p)
print(f(100) * ((P4 - f(1)) / j))                   # 37614.074